From Monolith to Microservices
The platform was already old when we started — a roughly ten-year-old Symfony 1 monolith with a single database, carrying years of business logic and accumulated technical debt.
We wanted to modernize it. The obvious question was how.
The organization didn’t want to commit to rewriting the entire platform from scratch. That would have meant a significant investment, a dedicated team and a long period before the business saw a return.
Microservices looked like an attractive alternative.
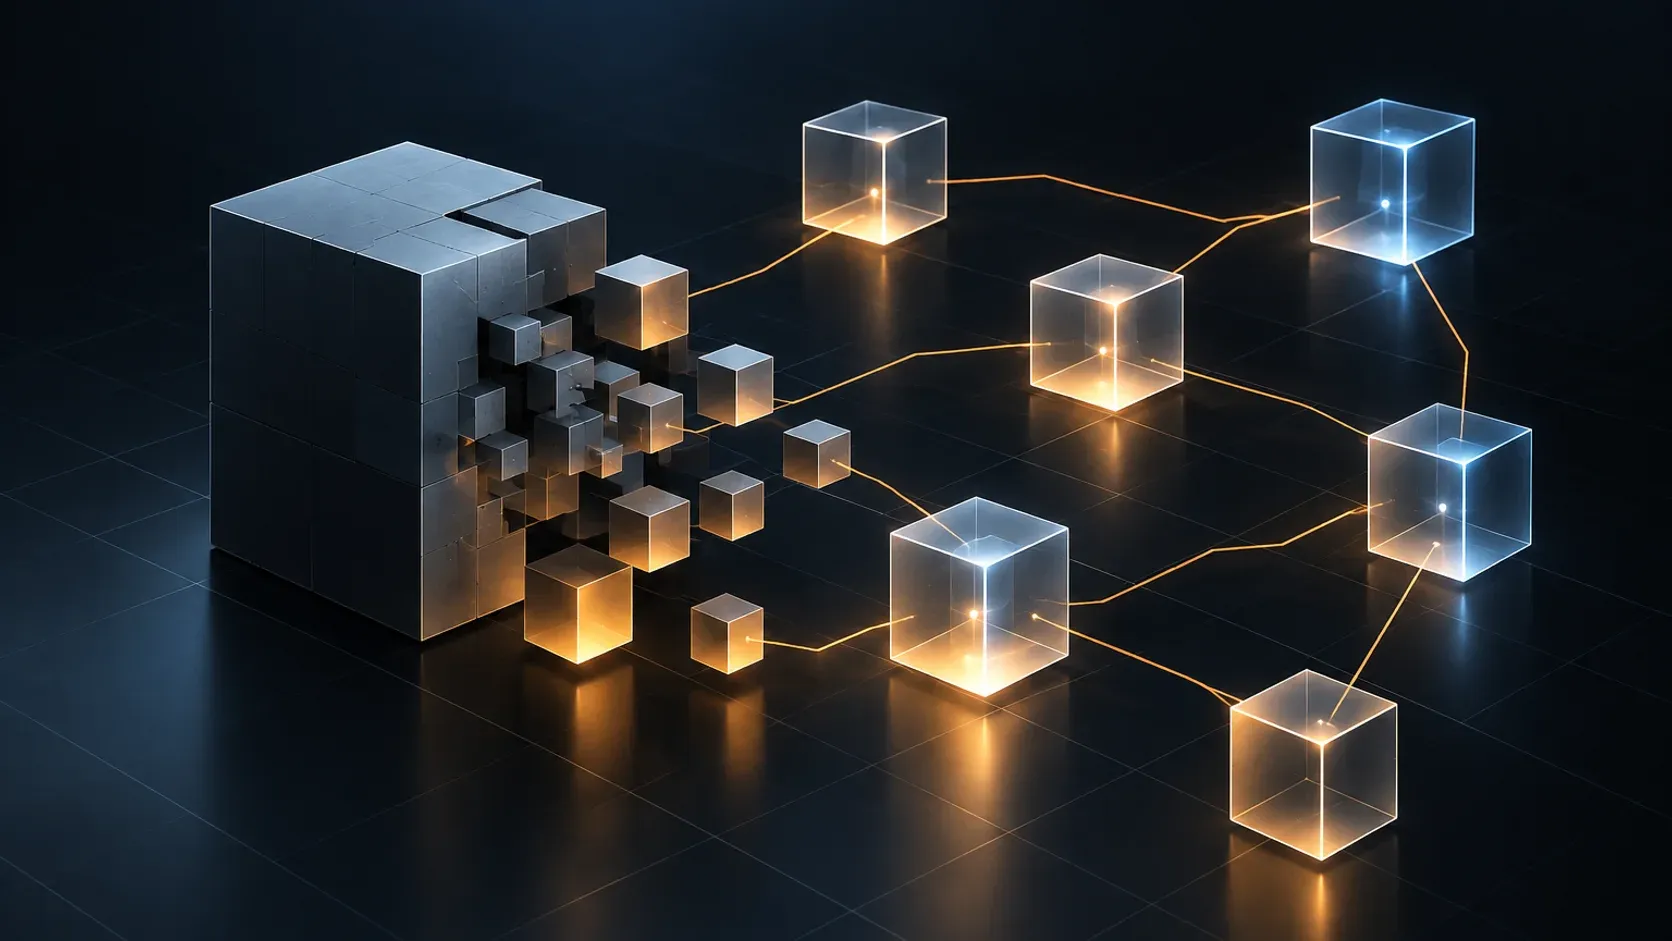
Instead of rewriting everything, we could gradually extract individual business domains from the monolith, build them as independent services and integrate them back into the existing platform.
On paper, it sounded like the best of both worlds.
I wasn’t convinced.
But there was significant management pressure to move in this direction, and eventually I became responsible for helping make it work.
We started identifying business domains that could potentially live independently: Users. Search. SEO. Email.
Each extracted service got its own:
- Codebase
- Database
- Kubernetes deployment
- Pods & resources
- Infrastructure
- API
The technology stack was deliberately modern compared with the legacy platform:
Symfony + API Platform + Apollo GraphQL + Kubernetes + Google Cloud
Istio handled service routing inside the Kubernetes environment.
Technically, it was a fascinating project. For someone who enjoys technology, there was a lot to learn.
We were building things that simply weren’t possible in the old monolith without significant effort, and the separation of services forced us to think much more carefully about boundaries, APIs and ownership.
After the first few services, however, the complexity started becoming impossible to ignore.
Breaking apart a monolith doesn’t remove complexity.
It moves it.
Inside a monolith, a database transaction can often guarantee that several related changes happen together. Once those pieces become separate services, that assumption disappears.
We started dealing with problems such as:
- Data consistency
- Distributed workflows
- Schema changes
- Service health and availability
- Rollbacks
- Cross-service dependencies
- Synchronization between systems
The old monolith had one database. Now we had multiple databases that needed to agree with each other.
And because the new services still had to coexist with the legacy platform, we often ended up synchronizing data in both directions. A service might call the legacy API. The legacy platform might need to persist information back into the service. Entities that had once been joined together inside a single database now had to communicate over APIs.
The clean boundaries we had drawn on an architecture diagram were considerably less clean in production.
This became one of the biggest lessons of the project.
We weren’t replacing the monolith. We were building new systems that still depended on it.
That meant the legacy platform remained a kind of umbilical cord connecting the new services to the old world.
Extracted domain → integration point → dependency → failure mode
Every extracted domain created another integration point. Every integration point created another dependency. And every dependency created another thing that could fail.
The architecture was becoming more distributed, but the old platform was still at the center of it.
We had gained independent services without actually gaining independence.
Apollo GraphQL was an interesting part of the stack. It gave us a flexible interface between the different parts of the system and was technically a very useful technology to work with.
But over time, more and more business logic started finding its way into the GraphQL layer.
That was a warning sign.
Instead of simply being a query/API boundary, GraphQL was gradually becoming another place where business behavior had to be maintained. We had introduced a new architectural layer to simplify communication, but that layer itself was becoming part of the complexity.
This is one of those things that looks elegant on an architecture diagram and becomes considerably more complicated once a real business starts changing underneath it.
This was the problem I had been concerned about from the beginning.
A microservice isn’t just a codebase. It’s an operational unit.
Five services don’t mean five pieces of code. They can mean:
5 databases + 5 deployments + multiple pods + networking + monitoring + logging + backups + CI/CD + infrastructure + operational ownership
And suddenly the infrastructure bill starts reflecting the architecture.
We had to explain why the infrastructure was growing. I had raised this concern early. But architecture risks are often difficult to make people care about before they become real costs.
Once the additional infrastructure existed and the bills arrived, the conversation changed. It became much harder to explain why something that had looked like a relatively small architectural improvement required significantly more infrastructure and operational effort.
And that was uncomfortable. Because I had warned about it.
Being right about a problem after it happens doesn’t make the problem any better.
Eventually management reached the conclusion that the technical benefits weren’t translating into enough business value.
The platform could be more resilient. It could potentially scale individual components independently. The architecture was more modern.
But customers weren’t going to pay more because we had microservices. And the organization couldn’t simply absorb the cost of rebuilding the platform indefinitely.
There was no clear business case for continuing the transformation at the scale originally imagined. Around five services were ultimately extracted, but the broader modernization remained unfinished.
That’s why I don’t consider this project a success story. It was a successful learning experience.
Those are not always the same thing.
You should only pay the price of a distributed system when you actually need what you’re buying.
I would probably make a different recommendation.
If the goal is to modernize a ten-year-old monolith, I would start with a modular monolith.
Keep a single deployable application initially, but create strong boundaries between business domains. Give those domains clear ownership of their code and data. Make the internal boundaries explicit.
Then extract a service only when there is a concrete reason to do so. For example:
- A domain needs to scale independently.
- A team needs to deploy it independently.
- A component has fundamentally different operational requirements.
- Organizational boundaries justify independent ownership.
And if the platform genuinely needs to be rebuilt, I would be much more explicit about the investment required. Don’t disguise a rewrite as a gradual microservices project simply because the organization is uncomfortable approving a rewrite.
Sometimes the honest answer is:
“We need to rebuild this platform, and that will cost money.”
That is a much healthier starting point than pretending we can get the benefits of a new platform without paying for one.
“The most valuable lesson wasn’t how to build a microservice. It was learning when not to build one.”
I genuinely enjoyed this project.
The technology was fascinating. I learned a huge amount about distributed systems, Kubernetes, service boundaries, APIs, consistency and the operational realities of running multiple independent services.
Today, I would not start with the question:
“Which parts of this monolith can we turn into microservices?”
I’d start with:
“What problem are we actually trying to solve, and what is the simplest architecture that solves it?”
Because sometimes the right answer isn’t five services. Sometimes it’s a better monolith.
And sometimes the right answer really is a complete rewrite.